TL;DR
GPT 5.6 Luna and Tencent Hy3 tied at 83.1% defect recall in the August 2026 artifact-review study. Luna repeated its grade on nineteen of twenty-three artifacts, versus eighteen for Hy3, supporting a small consistency preference in this sample. Reducers received the same mapper findings and could not recover defects missing from those inputs. The published table has no model billing or latency, and the results do not establish a universal review advantage.
Published results
23 hand-labeled artifacts covering 14 task types; 3 reducer models in the public table. Published 2026-08-08. Values retain their original units and grading scale.
Show the table · 3 rows, 3 columns
Scroll sideways to compare all columns. Select a heading to sort.
| openai/gpt-5.6-luna | 83.1% | 19 of 23 |
| tencent/hy3 | 83.1% | 18 of 23 |
| minimax/minimax-m3 | 82.5% | 16 of 23 |
No matching rows. Clear the filter to see all records.
23 hand-labeled artifacts covering 14 task types; 3 reducer models in the public table. Published 2026-08-08. Values retain their original units and grading scale.
What the result helps you choose
Luna and Hy3 tied at 83.1% defect recall. Luna repeated its grade on 19 of 23 artifacts, Hy3 on 18 and MiniMax on 16. That one-artifact difference supports a consistency preference in this sample; the table publishes no model cost or latency.
Review defects in delivered research: follow the published task
The reducer can assess only the defects supplied by its mappers. The repeated-grade count measures consistency separately from finding defects.
Source: 10 transactions and a Disney sale
The published Pelosi research checks 65 disclosure PDFs against 135 transactions read independently by eye. In the cited filing, the source contains 10 transactions; the Disney transaction is a sale.
These are public extraction errors used to explain what a reviewer must check.
Returned rows: 19 transactions and a Disney purchase
A sliding-window regex returned 19 transactions for the filing containing 10. Omitting the transaction-type filter turned the Disney sale into a purchase. Both errors left plausible-looking JSONL rows.
Compare the returned count and buy/sell direction with the original filing. A successful code exit does not establish either match.
Review: nine findings become six upheld defects
The published diagram gives OCR text, a rendered image, the native PDF, and code plus rows to four independent reviewers. Their nine findings reach one reducer: three are dropped as noise, six are upheld, and the displayed grade is B−.
This diagram illustrates the review mechanism. It is not identified as one of the 23 private benchmark artifacts or as a scored response from Luna, Hy3 or MiniMax.
Task and tested input
Judge defects in delivered research artifacts, including code and validation evidence.
Instruction in brief (task summary)
Given mapper findings, decide which defects are supported and assign a grade. A public example checks 65 Pelosi disclosure PDFs against 135 transactions read independently by eye.
Test against your own workload
Build a follow-up evaluation for your workload
Check whether the tested task and required output match your workload. Use a fixed set of representative examples, repeat the runs and inspect failures. Compare cost and latency alongside quality.
Each study lists the publication date and exact model versions. Use those dates when comparing the historical results with a model you can run today.
Calculate the decision from the measured rows
Published August 8, 2026. These counts measure consistency; they do not measure correct grading. Luna and Hy3 separately tie at 83.1% reported defect recall.
Show the table · 2 rows, 3 columns
Scroll sideways to compare all columns. Select a heading to sort.
| openai/gpt-5.6-luna | 83.1% | 19 of 23 |
| tencent/hy3 | 83.1% | 18 of 23 |
No matching rows. Clear the filter to see all records.
Both reducers found 83.1% of the hand-labeled defects. Luna repeated its grade on 19/23 reruns (82.61%), compared with Hy3's 18/23 (78.26%): one additional agreement in 23 tests. The measurable difference is consistency in this sample; recall is tied.
The reducers receive the same mapper findings. A missed mapper finding cannot be recovered by choosing a stronger reducer. Inspect the actual duplicate-row case on this page before interpreting the aggregate score as end-to-end review coverage.
How the runs worked
Read the test procedure
23 hand-labeled artifacts covering 14 task types; 3 reducer models in the public table
Map/reduce artifact grader versus independently hand-labeled defects
Step 1
Label defects in 23 artifacts across 14 task types.
Step 2
Give each reducer exactly the same mapper findings.
Step 3
Compare defect recall and whether rerunning keeps the same grade.
How to read the measurements
Grading and valid output
Defect recall is the share of hand-labeled defects found. Repeated-grade agreement counts artifacts assigned the same grade on a repeat; agreement alone does not prove correctness.
Cost
This comparison table has no per-model billing column.
Time
This table publishes no per-model latency.
Mapper / reducer
Mappers inspect parts of an artifact independently. The reducer combines their findings and assigns the final grade.
Sample and scope
A reducer cannot discover a defect absent from its mapper inputs. These results do not establish end-to-end recall for every arbitrary artifact.
GPT 5.6 Luna and Tencent Hy3 tie on reported defect recall (83.1%). Their repeated-grade counts differ by one in 23 tests; that is not evidence of a universal review advantage.
This is a task-specific snapshot. Current grader defaults and newer model versions are not inferred from an August publication.
Read the original evidence
Aurora product context
See the broader product workflow
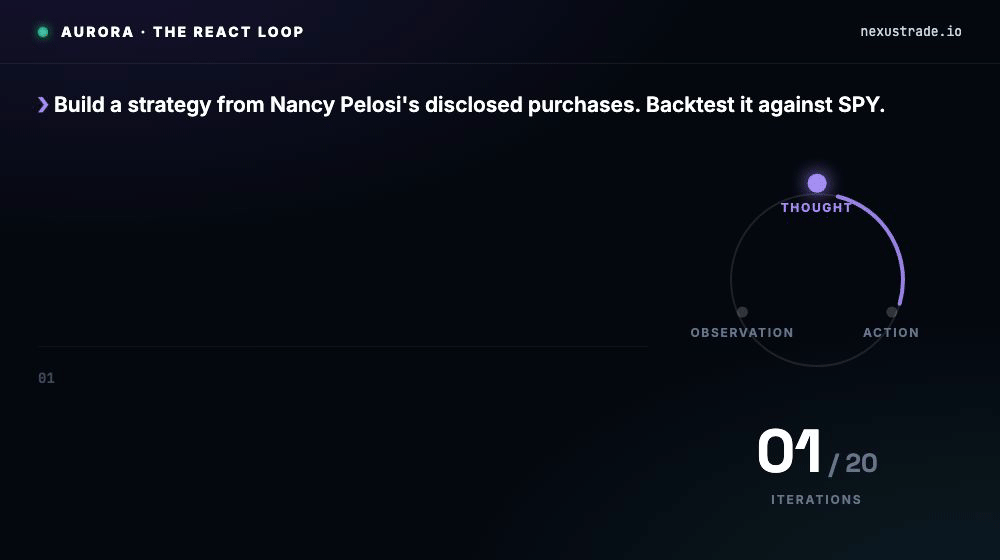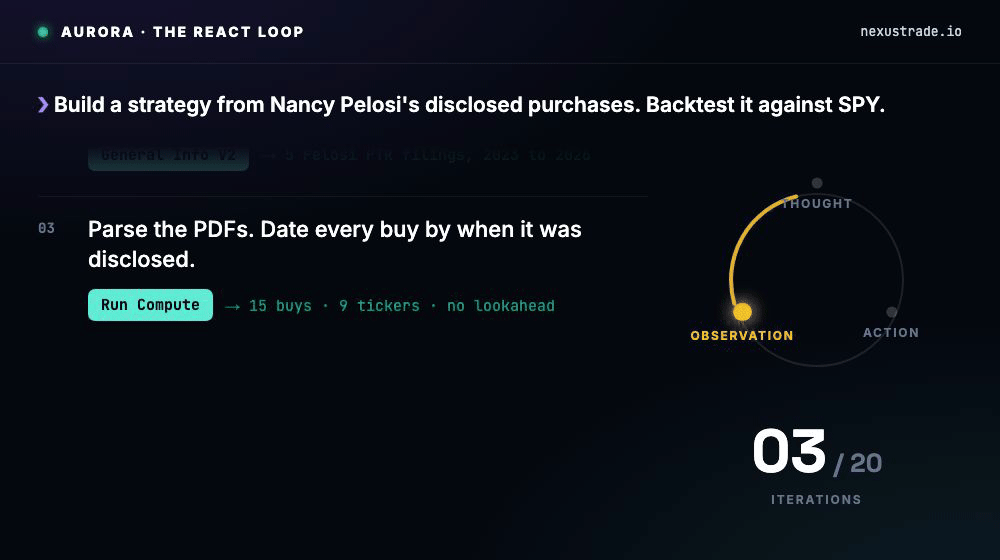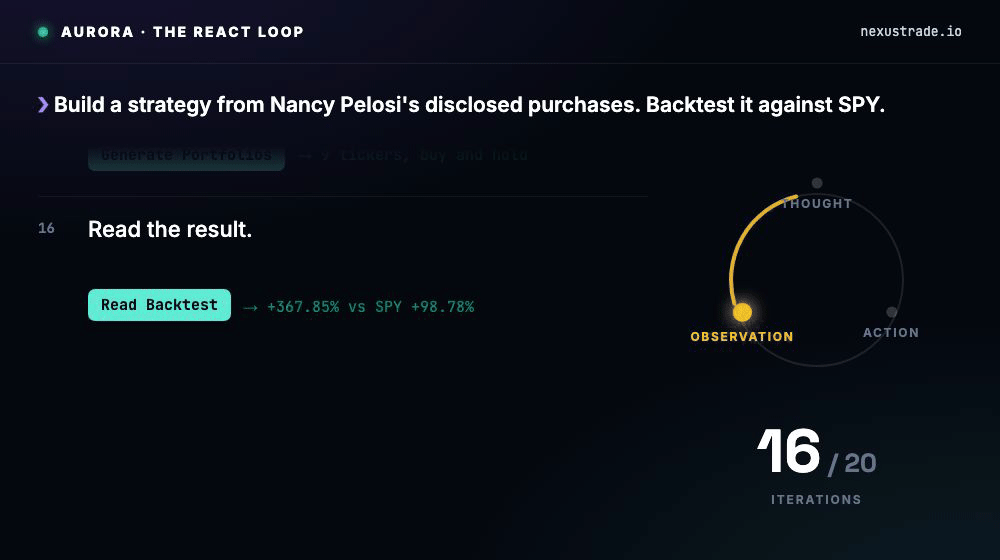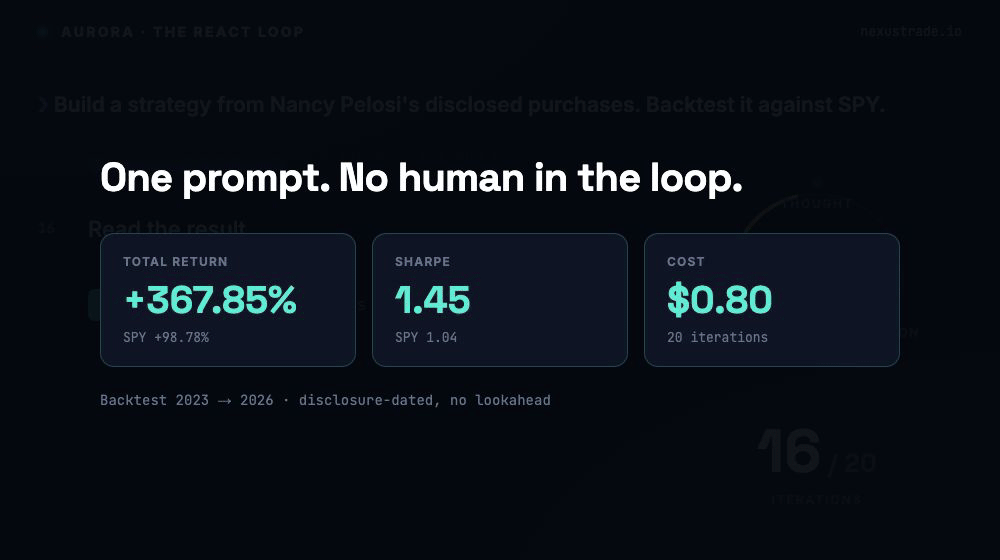
This August recording shows the broader Aurora agent workflow. The task explanations above describe each evaluation; its private conversations and complete system prompts remain private.
No comments yet.