TL;DR
The demonstrated signal append added one Friday row, moving the dataset from two rows to three and contentVersion 3; readback confirmed the updated samples. Signal rows upsert by timestamp, ticker and optional row ID, while generic-table dedupe settings do not apply. The proposed restore was never executed. Inspect current versions and downstream strategies before allowing a shrink, then read the dataset and linked indicator after any change.
Follow one worked path
Inspect the teaching rows
Use the exact calendar example below. Friday=1 and Monday=0 are teaching observations, not market prices or a profitable signal.
The example declares its row shape and public-availability semantics explicitly.
Append one signal row
Replace YOUR_DATASET_ID with your saved datasetId. Review this exact signal edit without dedupe_key, then read the row count and content version after any approved submission.
- After creation and availability materialization
- Rows: 2 · Dataset contentVersion: 2
- After one new Friday row
- Rows: 3 · Dataset contentVersion: 3
A successful response identifies your dataset and content version. Another person's identifier cannot address your dataset.
{
  "operations": [
    {
      "type": "appendRows",
      "dataset_id": "YOUR_DATASET_ID",
      "point_kind": "observation",
      "cascade_indicator": true,
      "rows": [
        {
          "timestamp": "2024-01-12T00:00:00.000Z",
          "value": 1,
          "row_id": "calendar-2024-01-12"
        }
      ]
    }
  ]
}Restore a recorded version deliberately
This restore was not executed. Read your actual versions, replace YOUR_DATASET_ID, and check downstream strategies before considering the version 2 shrink request.
A reviewed restore proposal is not a restored dataset. Read back current content and samples after any separately approved restore.
{
  "operations": [
    {
      "type": "restoreVersion",
      "dataset_id": "YOUR_DATASET_ID",
      "target_version": 2,
      "point_kind": "observation",
      "cascade_indicator": true,
      "allow_shrink": true
    }
  ]
}Read the saved version
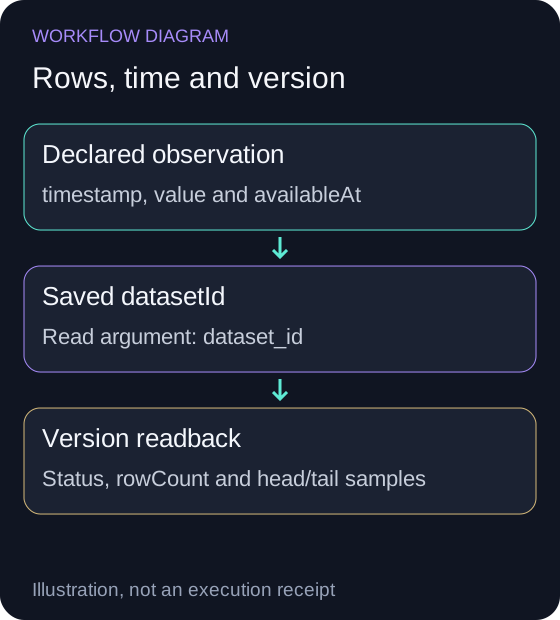
Pass datasetId as dataset_id to get_dataset. Check status, rowCount, version and head/tail rows; inspect the promoted indicator separately if requested.
The actual stored rows and version agree with the intended request. Restore or append only after checking the current saved head.
The append we completed
Show the table · 2 rows, 3 columns
Scroll sideways to compare all columns. Select a heading to sort.
| After creation and availability materialization | 2 | 2 |
| After one new Friday row | 3 | 3 |
No matching rows. Clear the filter to see all records.
Starting with the recorded initial two-row calendar dataset, we appended January 12, 2024, another Friday with value 1. The product returned one new row, three total rows and contentVersion 3. It also reported that the linked indicator was updated to dataVersion 2. A second get_dataset confirmed all three samples and status ready.
Append one signal row
Show append one signal row
Replace YOUR_DATASET_ID with your saved datasetId, then call edit_dataset. This is a signal dataset, so omit dedupe_key. The product upserts by timestamp, ticker and optional row_id; submitting the same signal row again does not create another distinct row. cascade_indicator true requests the linked-indicator update.
Our first request included dedupe_key and the product rejected it without changing the two-row dataset. Removing that field succeeded. A generic-table dedupe example must not be copied unchanged into a signal edit. After every edit, read the exact dataset again and compare samples and counts, not just the success message.
{
  "operations": [
    {
      "type": "appendRows",
      "dataset_id": "YOUR_DATASET_ID",
      "point_kind": "observation",
      "cascade_indicator": true,
      "rows": [
        {
          "timestamp": "2024-01-12T00:00:00.000Z",
          "value": 1,
          "row_id": "calendar-2024-01-12"
        }
      ]
    }
  ]
}
Restore a recorded version deliberately
Show restore a recorded version deliberately
This is a restore request for the two-row version in our demonstrated history. We did not run it. Read your actual versions first, choose the intended target_version, and review downstream strategies before submitting. Here allow_shrink true explicitly allows returning from three rows to two; it is not a default recommendation for a live signal.
Read the dataset after a restore and record the resulting current version and samples. Restoring content and selecting an old version number are different facts; do not claim a restored result until the readback shows it.
{
  "operations": [
    {
      "type": "restoreVersion",
      "dataset_id": "YOUR_DATASET_ID",
      "target_version": 2,
      "point_kind": "observation",
      "cascade_indicator": true,
      "allow_shrink": true
    }
  ]
}
Choose append or replacement
Show choose append or replacement
appendRows merges new signal rows by timestamp, ticker and optional row_id. Generic datasets can use dedupe_key. replaceContent changes the full content and refuses fewer signal points unless allow_shrink intentionally permits the smaller series. An append is not a full replacement.
Update the linked indicator
Show update the linked indicator
Signal append and replace operations cascade to the linked custom indicator by default. Declare point_kind and aggregate_period for the new rows. Use exact dataset_id or custom_indicator_id targets rather than guessing a name from prose.
Inspect row counts and availability after the operation. A transport success is not proof that the linked indicator contains the intended series.
Restore a saved version
Show restore a saved version
Use list_datasets to find the exact owned dataset_id and get_dataset to inspect its current samples. Request edits through edit_dataset with appendRows or replaceContent, then read that same dataset again and compare the expected row count and availability. restoreVersion selects a stored dataset version. Review its identity, coverage and downstream use before restoring; it changes current content. Keep the previous and restored version identifiers in your research notes.
These are supported editing operations, not a public data download. Private account datasets are never added to the public SEO catalog.
No comments yet.